

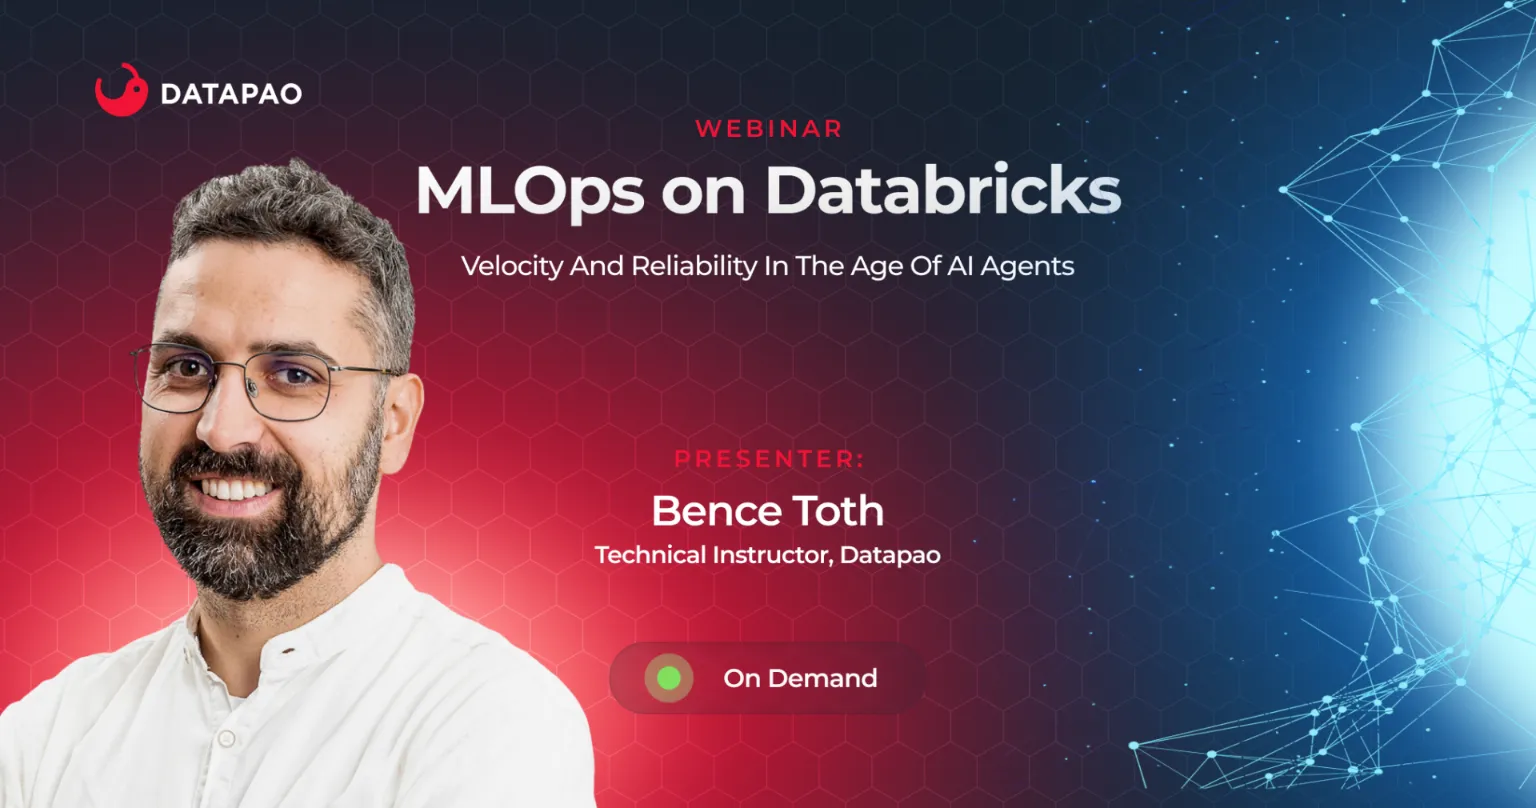
FROM FAST EXPERIMENTATION TO RELIABLE PRODUCTION MLOPS
Are you experimenting with the Databricks Data Science Agent, or planning to introduce GenAI-powered development into your ML workflows, and wondering how it will ever be production-safe?
Picture this: you’re a Data Scientist, ML Engineer, or Data Platform Lead. Your models come together faster than ever. Code appears in seconds. Experiments multiply.
But then comes the hard part: testing, governance, deployment, and long-term reliability. Auto-generated code is powerful, but it’s also non-deterministic. Without the right MLOps foundations, pipelines become fragile, environments drift, and production incidents become inevitable. But it doesn’t have to play out this way.
What if agent-generated notebooks could be transformed into reliable, governed, production-ready pipelines?
What if speed and stability didn’t have to compete?

In this engaging session, you’ll learn:
- How the Databricks Data Science Agent fits into real-world ML workflows
- What changes in MLOps when code is generated by AI agents
- How to structure, test, and modularize agent-generated code
- How to move from notebooks to production using: Lakeflow Jobs for orchestration; Databricks Asset Bundles (DABs) for config versioning; MLflow for model tracking, registry, and lifecycle management; Unity Catalog for governance, lineage, and access control
You’ll also see a live, end-to-end demo: From a natural language prompt in a Databricks notebook to automated deployment, testing, and monitoring in production.