

Adapt or fall behind: a review of the Databricks executive survey on AI and its use
Understand how 600 tech leaders think about AI and find out how to future-proof your business before adopting the emerging tech.
Global supply chains have never been under more strain, and the systems meant to manage them have never looked more dated. Most planning and logistics organizations still run on a patchwork: shipment tracking in one tool, production planning in an ERP, risk analysis in a spreadsheet, and forecasting that is often manual or missing entirely. Each system is reasonable on its own. Together, they leave the business without a single, trustworthy picture of what is actually happening.
The fragmentation is invisible right up until the moment it matters most. A port closes. A canal is blocked. A supplier misses a delivery, a weather event reroutes traffic through a key corridor, demand spikes without warning. In that moment, the questions are urgent and simple — Which shipments are affected? Is production at risk? What are my options, and how much time do I have? — but answering them means stitching together data from systems that were never designed to talk to each other. Teams get on the phone, export spreadsheets, and reconcile numbers by hand. By the time a clear picture emerges, the situation has already moved on, and the window to act well has narrowed or closed.
The financial weight of this is well documented across independent research. The Business Continuity Institute’s Supply Chain Resilience Report found that nearly 80% of organizations experienced at least one supply chain disruption over the prior twelve months — an increase on the year before (source: Business Continuity Institute, Supply Chain Resilience Report 2024, sponsored by Zurich Resilience Solutions). The cost of those shocks compounds over time: McKinsey finds that disruptions lasting longer than a month now occur every 3.7 years on average, and over the course of a decade can cost a company up to 45% of a single year’s profit (source: McKinsey, cited in the World Economic Forum, “Leveraging digital tools in the supply chain disruption era,” 2025).
What makes these shocks so damaging is that most companies cannot see far enough into their own networks to react in time. A survey of 240 supply chain leaders across Europe and the US by BCI Global found that only about one in three companies have the detailed, up-to-date end-to-end visibility needed to review and optimize their networks — leaving the other two-thirds, in the researchers’ words, driving in the dark (source: BCI Global, “No visibility – No resilient supply chain”). McKinsey’s 2025 supply chain survey echoes this, reporting that the majority of companies understand their supply chain risks only as far as their tier-one suppliers (source: McKinsey, “Decoding disruption to reshape manufacturing footprints,” 2026).
This is not a tooling inconvenience but more of a structural disadvantage. Disruption is now a constant rather than an exception, and the organizations that absorb it best are the ones that can see across their whole chain and respond in the time it takes a competitor to schedule a meeting.

The obvious response is “add AI.” Forecast the demand, predict the disruptions, automate the rerouting. In practice, most supply chain AI initiatives stall before they deliver, and the reasons are rarely about the models themselves.
The numbers bear this out, and they are sharpest in the supply chain specifically. Across industries, McKinsey’s State of AI in 2025 survey found that while a large majority of organizations now use AI in at least one function, only about one-third report having scaled it across the enterprise — leaving most stuck in what the report’s commentators describe as “pilot purgatory,” running experiments that never reach production. McKinsey identifies data quality and architecture as a leading blocker, noting that scaling AI requires clean, integrated, well-governed data rather than the siloed spreadsheets and legacy databases most organizations actually run on (source: McKinsey & Company, “The state of AI in 2025,” surveying nearly 1,500 organizations worldwide).
Gartner’s supply-chain-specific research points to the same wall. In one Gartner survey, only 23% of supply chain leaders reported having a formal AI strategy in place, with most chief supply chain officers focused on project-by-project short-term wins rather than transformational investment (source: Gartner, Inc., press release, June 2025, survey of 120 supply chain leaders). A separate Gartner study found that just 17% of supply chain organizations are pursuing immediate transformational redesign of their processes, while 83% are applying AI incrementally to legacy workflows — and Gartner names technology integration as a key roadblock to scaling AI in the supply chain (source: Gartner, Inc., press releases, 2026, surveys of 140 senior supply chain leaders). Gartner has also forecast that 60% of supply chain digital adoption efforts will fail to deliver their promised value by 2028 (source: Gartner, Inc., press release, May 2025). In supply chain, the prerequisite for AI success — unified, trustworthy, real-time data — is exactly what the fragmented systems landscape fails to deliver.
The first barrier is data foundations. AI needs a unified, real-time, trustworthy view of operations to reason over, and that is exactly what the fragmented landscape above fails to provide. Teams discover that the hard part isn’t the algorithm — it’s that the operational state lives in one silo, history in another, and the two were never reconciled. Most AI projects quietly become data-integration projects, and many die there.
The second barrier is the gap between analytics and operations. A model that produces a clever forecast in a notebook is not the same as a system that acts on live data and surfaces a recommendation to a planner at the moment of decision. Bridging that gap traditionally means standing up and integrating a separate operational database alongside the analytical platform and maintaining brittle plumbing between them. The engineering overhead is significant, and it is where ambition often outruns delivery.
The third barrier is trust and adoption. Planners will not hand decisions to a black box. AI has to start by augmenting people, making the current state legible, showing its reasoning, and leaving the human in control before anyone will let it automate. A system that can’t first earn that trust never gets the chance to deliver its more advanced capabilities.
The result is a familiar pattern: organizations know they need AI in the supply chain, invest in it, and stall on foundations, integration, and adoption long before they see value.

Datapao built the Supply Chain Visualization and Simulation Platform to remove those barriers rather than work around them. It is not a point tool and it is not a one-off dashboard. It is an accelerator, a foundation on Databricks that collapses the fragmented landscape into a single real-time view and gives organizations the data backbone, the operational layer, and the AI-ready architecture in one place, so that the months normally lost to integration and plumbing are already behind you on day one.
The principle behind it is straightforward to state and hard to deliver: one unified view of past, present, and future. A single place to see where every shipment is right now, how those shipments connect to production demand, and what happens when something goes wrong — with the ability to simulate disruptions and responses before committing to them in the real world.
A note on scope before we go further: while the examples below use ocean freight, nothing about the platform is specific to ships. The same engine models any mode of transport: air freight, rail, trucking fleets, last-mile delivery, or any combination across a multi-leg journey. A “route” can be a sea lane, a flight path, or a highway corridor; a “shipment” can be a container, a pallet on a truck, or an air cargo unit. Wherever goods move, and a disruption can delay them, the same visibility, rerouting, and scenario analysis apply.
The heart of the platform is a single operational view that unifies what is normally scattered across systems. A global map shows the transport network — in our reference scenario, 51 sea lanes connecting 41 ports along real shipping corridors — with every active shipment plotted against it: origin, destination, cargo, progress, and live status.
That alone replaces several disconnected tracking tools. The decisive step is connecting that movement to production. Every facility has a production target and a bill of materials, and the platform ties the components in transit directly to the demand they are meant to satisfy.
A planner can immediately answer the question that usually takes a morning of cross-referencing: is my production going to be on time, or do I have a problem incoming? When components haven’t shipped, the affected production is flagged as at risk, not after a reconciliation cycle, but as the live state of the system. Filtering by criticality, risk, or reroute status turns a sprawling operation into a short list of exactly the things that need attention.

The platform’s value shows most clearly under disruption, because that is where fragmented systems fail and where time is most expensive.
When a disruption occurs — e.g. a blockage in the Suez Canal — the affected shipments are flagged instantly and visibly. There is no scramble across systems to determine what’s impacted; the answer is already on screen. The platform then reroutes affected shipments automatically (around the Cape of Good Hope, in this case), recalculating ETAs, distances, and arrival times with no manual intervention. The original and detour routes are shown side by side, so the trade-off is transparent rather than hidden. The entire loop — from a user triggering a disruption to seeing its downstream production impact on screen — completes in under 200 milliseconds.
Crucially, the impact is traced all the way through to production. A dedicated view surfaces the shipments that will no longer arrive in time and lets planners reason about responses — sourcing a component from a closer supplier, adjusting a production schedule — and see the effect immediately. Changing the sourcing hub for one shipment, for example, might close a production gap by a week. In a single connected motion, a disruption to a vessel in the Indian Ocean is traced to its consequence on a factory floor in Hamburg, and a response is chosen in seconds.
And because planners often know things the system does not (e.g. an anticipated port strike, a shift in customer priority) they remain in control. Any shipment can be rerouted manually: the planner selects it, reviews the offered alternative routes, and commits to one, with the platform handling the recalculation from there. The same transactional layer the engine computes against is the one that the user writes to — elevating this solution from a read-only visualization to a closed-loop control system. This is the augmentation-before-automation principle in practice: the system earns trust by making the planner more capable, not by sidelining them.
Beyond shipments, the platform gives production and inventory teams their own lens on the same unified data. For each facility, it shows what is in stock, what is in transit, and the gap against the production plan, ingredient by ingredient.
Production health is made legible at a glance: a clear signal of whether a facility is producing or stalled waiting on materials, which components carry a comfortable buffer and which are running thin, and how a slipping shipment moves those lines. The logistics team watches the network; the production team watches the floor — both reading from one source of truth rather than two reconciled spreadsheets.
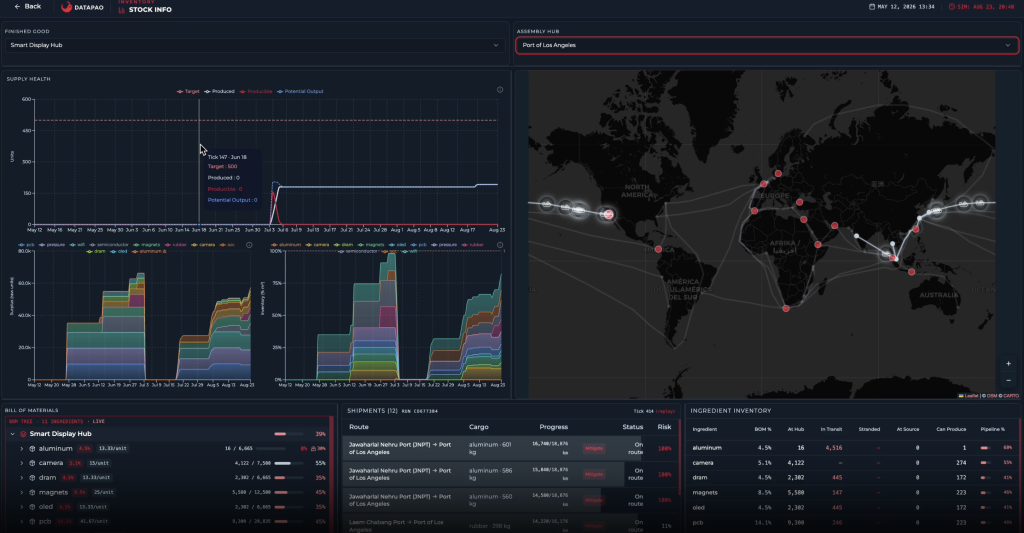
One of the platform’s most strategic capabilities is that the same engine driving the live view also runs forward-looking simulations. It generates realistic asset movements along real corridors with configurable disruption events — which makes for a compelling demonstration, but more importantly turns the platform into a scenario-analysis tool for real decisions.
What if the canal stays blocked for a week? What if we increase safety stock? What if we re-source from a different supplier?
These questions can be answered against the organization’s real network and production targets before any commitment is made. This moves planning from reactive firefighting to deliberate, evidence-based decisions, and it is a capability the fragmented status quo cannot offer at all.

The platform is built to resolve, rather than inherit, the data-foundation problem that stalls most supply chain AI. It rests on two complementary layers within Databricks.
Databricks and Delta Lake form the analytical layer — history, aggregations, and the simulation engine itself — giving the platform deep analytical depth and a foundation that machine learning can build on directly.
Lakebase, Databricks’ managed PostgreSQL, holds the live operational state. This is the layer that bridges the analytics-to-operations gap described earlier, and it is detailed in its own section below.
The categorization and rerouting logic today is rule-based, but this is a deliberate starting point, not a ceiling. Because the operational and analytical layers already share one foundation, there is no integration project standing between the platform and its next stage. The building blocks are in place to layer on-demand forecasting, anomaly detection, and automated recommendations — letting machine learning progressively take over decisions on top of data that is already unified and real-time. The platform is an accelerator precisely because it delivers the foundation that AI needs on day one.
The responsiveness at the core of the platform — assets moving in real time, ETAs recalculating, a disruption flagging an affected shipment the instant it happens — comes down to how the live state of the world is stored. For that, Datapao built on Lakebase, Databricks’ managed PostgreSQL.
A supply chain control tower has an unusual requirement that sits at the root of the AI-adoption problem. It needs the fast, transactional read-and-write behavior of an operational database to track the live state of every shipment, and it needs that same data to sit naturally alongside a deep analytical layer for history and simulation. The traditional approach — running a separate operational database next to the analytics platform and maintaining fragile plumbing between the two — is exactly the integration overhead that stalls so many projects. Lakebase let us avoid that split entirely.
Every asset position, every ETA recalculation, and every status change — from in transit to critical to rerouted or mitigated — is written to and read from Lakebase as it happens. When the simulation advances, those updates land immediately, and the view reflects them with no batch job in between. Every tick commits atomically in a single database transaction, so the view never shows a half-updated state. This is what makes the disruption response feel instant: the moment a blockage flags an affected shipment, the new state is already stored and on screen.
Because Lakebase is managed PostgreSQL, it runs on familiar ground — standard SQL, standard drivers, and no separate database tier to stand up or operate. That removes a major source of the engineering overhead that derails operational-AI initiatives. And because it lives inside the Databricks platform alongside Delta Lake, the live operational state and the historical analytical data are not separated by a system boundary. That closeness is what lets the platform trace a single disruption from an asset in transit all the way to a production gap on a factory floor, with the live state and its analytical context always in reach of each other.
This same foundation is what makes the platform mode-agnostic. The operational state in Lakebase doesn’t care whether a moving asset is a vessel, an aircraft, a rail car, or a truck — it is the same pattern of positions, ETAs, and status changes streaming in and being read back instantly. Adding a new transport mode, or running ocean, air, and road freight side by side in one view, is a matter of feeding Lakebase the relevant operational data, not re-architecting the system. The transactional store scales with the fleet, whatever that fleet is made of.
In short, Lakebase is what turns this from a dashboard that shows data into a control tower that operates on live state — an operational database with the transactional feel users expect, on the same foundation as the analytics and AI that build on top of it.
The fragmented supply chain is a solved problem the moment an organization stops trying to reconcile silos and starts operating from one unified, real-time foundation. That is what Datapao built: a platform that brings past data, present state, and future simulation into a single system, works across any transport mode and any production target, and is engineered from the ground up to be the foundation that supply chain AI actually needs.
For the organizations adopting it, the shift is concrete. Instead of scrambling across disconnected systems when something breaks, teams see the whole chain at once, understand the impact in seconds, and act — with the system augmenting their judgment today and ready to automate more of it tomorrow. The accelerator removes the months normally lost to foundations and integration, so the work that remains is the work that creates advantage.
Interested in how this could connect to your own logistics and ERP systems, span your full transport network, or be extended with AI-driven forecasting and recommendations? Get in touch with the Datapao team.
Datapao is a Databricks-focused data and AI consulting and training company operating in the UK and across Europe, with delivery hubs in the UK and Central Europe. The company helps organisations design, build, and operate modern data platforms while enabling internal teams through hands-on Databricks training. Our approach combines deep engineering expertise with structured knowledge transfer to ensure sustainable, long-term adoption of data and AI.
Get in touch to discuss where to start.
Supply chain disruption and visibility
AI adoption and scaling
Understand how 600 tech leaders think about AI and find out how to future-proof your business before adopting the emerging tech.
Understanding the two most popular cloud-based data platforms helps to make an informed decision.


